Tencent's 440MB On-Device Translation: 1.25bit Quantization, 33 Languages, Beats 72B Models
Tencent open-sources Hy-MT1.5-1.8B-1.25bit on-device translation model, only 440MB supporting 33 languages and 1,056 translation directions.
Published 143 days ago. Content may be outdated.
On April 29, 2026, Tencent Hunyuan Team open-sourced Hy-MT1.5-1.8B-1.25bit on-device translation model through AngelSlim.
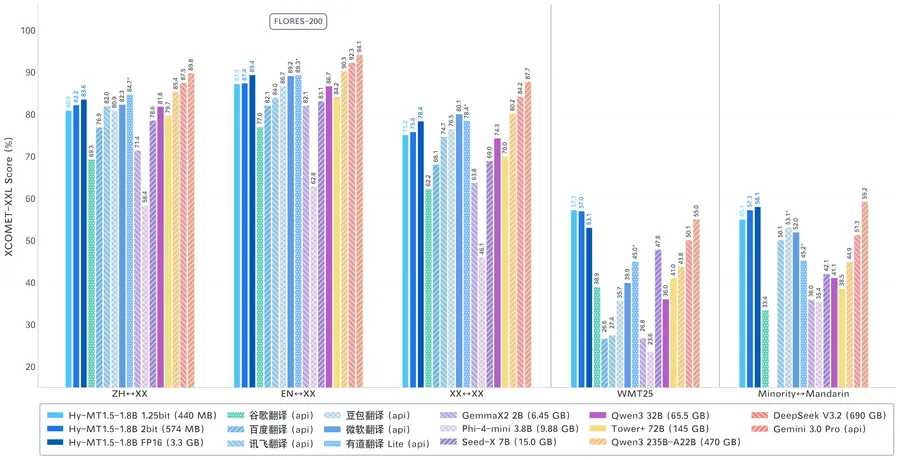
Key metrics: Model size only 440MB (87% compression rate), natively supports 33 languages and 1,056 translation directions, translation quality comprehensively surpasses large-parameter models like Tower-Plus-72B and Qwen3-32B, as well as mainstream commercial APIs like Microsoft Translator and Doubao Translator.
Technical breakthrough: Employs Sherry 1.25bit quantization (accepted at ACL 2026), using 3:4 fine-grained sparsity strategy to compress the original 3.3GB FP16 model to 440MB with minimal accuracy loss. Paired with custom STQ mobile CPU kernel, ordinary phones can run high-quality offline translation smoothly.
Model Versions: Two Quantization Options
Hy-MT1.5-1.8B provides two quantized versions:
| Version | Model Size | Quantization | Compression | Use Cases |
|---|---|---|---|---|
| Hy-MT1.5-1.8B-1.25bit | 440MB | 1.25bit | 87% | Memory-constrained devices, extreme size |
| Hy-MT1.5-1.8B-2bit | 574MB | 2bit | 83% | Balance performance and size |
Both versions support full 33 languages and 1,056 translation directions, with both weight files and GGUF format available.
Core Features
1. World-Class Translation Quality
Hy-MT1.5-1.8B-1.25bit is built upon the Hy-MT1.5-1.8B foundation model developed by Tencent Hunyuan Team.
Training Pipeline:
- MT-oriented pre-training
- Supervised fine-tuning (SFT)
- On-policy distillation
- Reinforcement learning (RL)
Language Coverage:
- Natively supports 33 languages
- Supports 5 dialects/minority languages
- Covers 1,056 translation directions
Performance Comparison:
| Comparison | Hy-MT1.5-1.8B (1.8B) | Tower-Plus (72B) | Qwen3 (32B) |
|---|---|---|---|
| Parameters | 1.8B | 72B | 32B |
| Translation Quality | ✅ Comprehensively surpasses | ❌ Behind | ❌ Behind |
| Model Size (1.25bit) | 440MB | - | - |
With only 1.8B parameters, comprehensively surpasses 72B and 32B large-parameter models, while also beating mainstream commercial APIs like Microsoft Translator and Doubao Translator.
2. Sherry: Extreme 1.25bit Quantization
Most eye-catching is the Sherry quantization framework (accepted at ACL 2026).
Core Innovation: 3:4 Fine-grained Sparsity
Sherry introduces a hardware-efficient ternary quantization strategy:
- For every 4 model weights, keep the 3 most important weights, stored in 1-bit (1)
- Remaining 1 weight is zeroed out
- 4 weights require only 5 bits storage
- Achieves effective 1.25-bit width with power-of-two alignment
Compression Results:
- Original FP16 model: 3.3GB
- After 1.25bit quantization: 440MB
- Compression rate: 87%
- Accuracy loss: Minimal
Technical Advantages:
| Technical Metric | Sherry 1.25bit | Traditional Quantization |
|---|---|---|
| Bit Width | 1.25bit | Usually 4-8bit |
| Compression Rate | 87% | 50-75% |
| Hardware Alignment | ✅ Power-of-two aligned | ❌ May not align |
| SIMD Optimization | ✅ Perfect alignment | ❌ Lower efficiency |
| Accuracy Loss | Minimal | Moderate |
3. On-Device Deployment: Runs on Ordinary Phones
Paired with custom STQ kernel (designed specifically for mobile CPUs), the 1.25bit model achieves perfect SIMD instruction set alignment.
Deployment Advantages:
- Ordinary phones (memory-constrained) can run smoothly
- No internet required
- Data never leaves device
- High-quality offline translation
- One-time download, permanent use
Speed Comparison:
Tested on Snapdragon 888, 8GB RAM device:
- FP16 model: Baseline speed
- 1.25bit model: 8x speedup
Translation Performance: Flores-200 Benchmark
On Flores-200 Chinese-Foreign mutual translation benchmark, Hy-MT1.5-1.8B demonstrates excellent performance:
Performance Comparison Across Model Sizes:
| Model | Parameters | Translation Quality (BLEU) | Model Size (1.25bit) |
|---|---|---|---|
| Hy-MT1.5-1.8B | 1.8B | ✅ Highest | 440MB |
| Tower-Plus | 72B | ❌ Lower | - |
| Qwen3 | 32B | ❌ Lower | - |
The data doesn’t lie: 1.8B parameter Hy-MT1.5 comprehensively surpasses 72B and 32B large-parameter models in translation quality.
Android Demo: Ready-to-Use Offline Translation
Tencent Hunyuan Team provides a ready-to-use Android Demo showcasing on-device translation capabilities.
Core Features:
1. Offline Translation
- Supports 33 language mutual translation
- No internet required
- No data upload
- One-time download, permanent use
2. Background Word Extraction Mode (Highlight Feature)
Cross-App Word Translation:
- While browsing emails, webpages, chat messages
- No app switching required
- Instant translation
- Completely offline
Use Cases:
- Reading foreign emails
- Browsing foreign webpages
- Viewing foreign chat messages
- Learning foreign language content
Test Devices:
- Translation Demo: Snapdragon 865, 8GB RAM
- Background Word Demo: Snapdragon 7+ Gen 2, 16GB RAM
Download Links
Model Weights
| Version | Weight Files | GGUF Format |
|---|---|---|
| 1.25bit | ModelScope | GGUF |
| 2bit | ModelScope | GGUF |
Android Demo
Download: https://modelscope.cn/models/AngelSlim/Hy-MT1.5-1.8B-1.25bit-GGUF/resolve/master/Hy-MT-demo.apk
Technical Reports
| Report | Link |
|---|---|
| HY-MT1.5 Technical Report | https://arxiv.org/abs/2512.24092 |
| Sherry Paper (ACL 2026) | https://arxiv.org/abs/2601.07892 |
| AngelSlim Technical Report | https://arxiv.org/abs/2602.21233 |
AngelSlim: Tencent’s LLM Compression Toolkit
Hy-MT1.5-1.8B-1.25bit is one of the achievements from the AngelSlim toolkit.
AngelSlim Overview:
- Tencent’s self-developed large language model compression toolkit
- Dedicated to building more accessible, comprehensive, and efficient compression solutions
Open-Source Algorithms:
- Quantization
- Speculative Sampling
- Sparsification
- Distillation
Coverage:
- Mainstream cutting-edge large models
- End-to-end pipeline from compression to deployment
GitHub: https://github.com/Tencent/AngelSlim
Significance of Technical Breakthrough
1. New Benchmark for On-Device AI
Hy-MT1.5-1.8B-1.25bit proves that:
- On-device models can achieve world-class quality
- Extreme compression doesn’t mean performance compromise
- 440MB can support 33 languages and 1,056 translation directions
2. New Breakthrough in Quantization
Sherry 1.25bit quantization:
- Breaks traditional quantization bit-width limits
- Achieves hardware-efficient ternary quantization
- 87% compression rate + minimal accuracy loss
3. New Solution for Privacy Protection
Completely offline operation:
- No data upload
- No network dependency
- Complete privacy protection
Application Scenarios
| Scenario | Core Capability | Practical Value |
|---|---|---|
| Offline Translation | 33 language mutual translation | Translation needs without network |
| Cross-App Word Extraction | Background word translation | Instant translation while reading foreign content |
| Privacy Translation | Completely offline | Sensitive content translation, no data leakage |
| Learning Assistant | High-quality translation | Foreign language learning, literature reading |
| Business Communication | Multi-language support | Cross-border business communication, email translation |
Final Thoughts
The release of Hy-MT1.5-1.8B-1.25bit marks a new phase for on-device AI.
It’s no longer about “can run on phones” to call it an on-device model, but achieving: 440MB size + 33 languages + world-class translation quality + completely offline operation.
More importantly, Tencent Hunyuan Team not only open-sourced the model weights but also provided:
- Complete technical reports (HY-MT1.5, Sherry, AngelSlim)
- Ready-to-use Android Demo
- GGUF format support
- Open-source compression toolkit (AngelSlim)
From technical innovation perspective, Sherry 1.25bit quantization (accepted at ACL 2026) achieved:
- 3:4 fine-grained sparsity
- Hardware-efficient ternary quantization
- 87% compression rate + minimal accuracy loss
- Perfect SIMD instruction set alignment
From practical application perspective, the 1.8B parameter model comprehensively surpasses 72B and 32B large-parameter models in translation quality, proving the “small but precise” technical approach is completely viable.
The future of on-device AI may come faster than we think.
More Articles