
Tencent Hunyuan HY-MT 1.5: 33-Language Translation Model, Small Size Big Results
Tencent Hunyuan HY-MT 1.5 translation model tutorial - upgraded WMT25 champion version supporting 33 languages, 1.8B model matching 7B performance, with deployment code and Docker images
Published 262 days ago. Content may be outdated.
What Is This?
Tencent Hunyuan recently open-sourced HY-MT 1.5, a large language model specifically designed for translation. It supports 33 languages, including Cantonese and Traditional Chinese dialects.
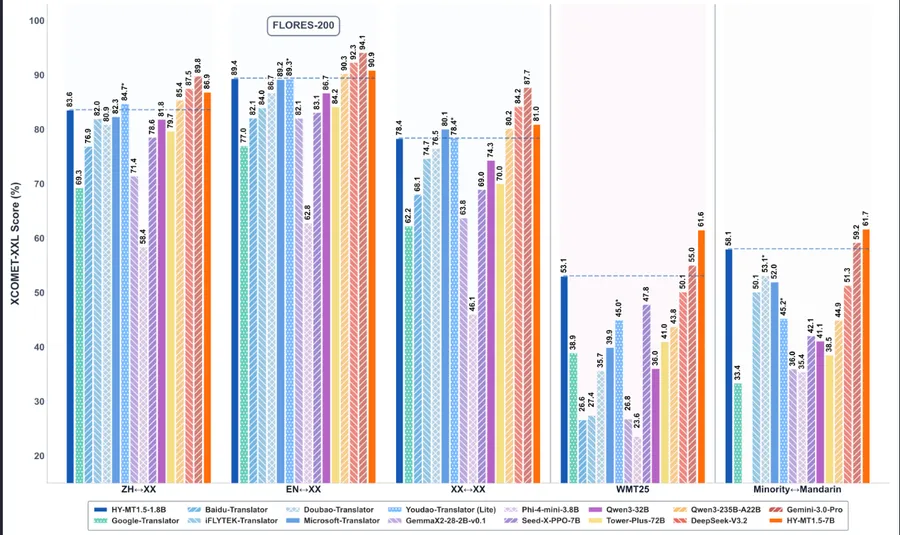
Most impressively, this model is an upgraded version of the WMT25 (top-tier machine translation competition) champion model, delivering exceptional translation quality.
Project URL: https://github.com/Tencent-Hunyuan/HY-MT
Key Highlights
Small Model, Big Performance
HY-MT offers two versions:
| Version | Parameters | Description |
|---|---|---|
| HY-MT1.5-1.8B | 1.8 Billion | Lightweight version, ideal for mobile and real-time translation |
| HY-MT1.5-7B | 7 Billion | Full version, best performance |
Here’s the key point: The 1.8B small model performs almost as well as the 7B version. With only one-third of the parameters, translation quality is nearly identical - great news for developers looking to run translation on mobile or edge devices.
Three Practical New Features
- Terminology Intervention - Specify how professional terms should be translated (medical, legal terminology, etc.)
- Context-Aware Translation - Uses context for more coherent translations
- Format-Preserving Translation - Maintains original document formatting, convenient for document translation
Language Coverage
Supports 33 languages including Chinese, English, Japanese, Korean, French, German, Russian, Arabic, and more. Plus 5 additional dialect/variant options (Cantonese, Traditional Chinese, etc.).
Model Downloads
Tencent provides multiple quantized versions for those with limited GPU memory:
       HY-MT1.5-1.8B          # Base version
HY-MT1.5-1.8B-FP8      # FP8 quantization
HY-MT1.5-1.8B-GPTQ-Int4 # Int4 quantization, lowest memory usage

HY-MT1.5-7B            # Standard version
HY-MT1.5-7B-FP8        # FP8 quantization
HY-MT1.5-7B-GPTQ-Int4  # Int4 quantization
How to Use?
Transformers Inference
The simplest approach - just install transformers and run:
       from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "tencent/HY-MT1.5-7B"
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(model_name)

prompt = "Translate the following Chinese to English: Artificial intelligence is changing our way of life."

inputs = tokenizer(prompt, return_tensors="pt")
outputs = model.generate(
    **inputs,
    top_k=20,
    top_p=0.6,
    repetition_penalty=1.05,
    temperature=0.7,
    max_new_tokens=256
)

result = tokenizer.decode(outputs[0], skip_special_tokens=True)
print(result)
Official recommended parameters: top_k=20, top_p=0.6, repetition_penalty=1.05, temperature=0.7
Docker One-Click Deployment
For those who don’t want to deal with environment setup, use the official Docker image:
       docker pull hunyuaninfer/hunyuan-7b:hunyuan-7b-trtllm

docker run -d --gpus all \
  -p 8000:8000 \
  hunyuaninfer/hunyuan-7b:hunyuan-7b-trtllm
Supported Inference Frameworks
Besides Transformers, these mainstream frameworks are also supported:
- TensorRT-LLM - For maximum performance
- vLLM - High-concurrency service deployment
- SGLang - Flexible inference engine
Want to Fine-tune?
Use the LLaMA-Factory framework:
       # Single machine training
llamafactory-cli train examples/hy-mt/sft.yaml

# Multi-node distributed training
torchrun --nproc_per_node=8 \
  llamafactory-cli train examples/hy-mt/sft.yaml
For example, if you want to optimize translation for medical documents, just prepare your dataset and fine-tune.
Ideal Use Cases
- Real-time Translation Apps - 1.8B version is sufficient and fast
- Document Translation - Format-preserving translation maintains layout
- Professional Domains - Terminology intervention ensures accuracy
- Translation Services - 7B + vLLM for high-throughput deployment
- Multilingual Customer Service - 33 languages for instant translation
Where to Download?
- Hugging Face: tencent/HY-MT1.5-7B
- ModelScope: Search for HY-MT on ModelScope
- GitHub: Tencent-Hunyuan/HY-MT
Summary
As an upgraded version of the WMT champion model, HY-MT 1.5 has several clear advantages:
- 1.8B small model approaches 7B performance, deployment-friendly
- Terminology intervention and context-aware translation are practical features
- 33 languages + dialects for broad coverage
- Multiple quantized versions and inference framework support
If you’re working on multilingual projects, this model is worth trying.
More Articles
Related Posts
- 1 Tencent's 440MB On-Device Translation: 1.25bit Quantization, 33 Languages, Beats 72B Models
- 2 HunyuanOCR Tutorial: 1B Param Model Outperforms DeepSeek/PaddleOCR/Qwen | Deployment Guide
- 3 Open Source Pdf Translation Tool(PDFMathTranslate) - Format-Preserving Multilingual PDF Translation Tool with AI Integration