Kimi K2.5 Review: Crushes GPT-5.2 in Vision, Chases Claude in Coding, Pioneers Agent Swarm
Kimi K2.5 review: Beats GPT-5.2 in vision (9/17 benchmarks), approaches Claude 4.5 in coding, exclusive Agent Swarm 4.5x faster. Full comparison vs top AI models reveals strengths & gaps.
Published 244 days ago. Content may be outdated.
Moonshot AI January 27, 2026 announced Kimi K2.5, the most powerful open-source model to date. Building on K2 with continued pretraining over approximately 15 trillion mixed visual and text tokens, K2.5 delivers state-of-the-art coding and vision capabilities as a native multimodal model, along with a groundbreaking self-directed agent swarm paradigm.
The most striking innovation in K2.5 is its Agent Swarm capability: for complex tasks, K2.5 can self-direct a swarm of up to 100 sub-agents, executing parallel workflows across up to 1,500 tool calls. Compared with single-agent setups, this reduces execution time by up to 4.5x. The agent swarm is automatically created and orchestrated by K2.5 without any predefined subagents or hand-crafted workflows.
Core Capability 1: Visual Coding - Write Code from Images/Videos
K2.5’s biggest highlight is visual coding capability. Simply put: show it an image or video, and it generates the corresponding code.
| Capability | What It Does | Real-World Use |
|---|---|---|
| Video-to-Code | Watch a website demo video, generate complete code | Quickly replicate website interfaces |
| Image-to-Interface | Upload design mockup, auto-generate frontend code | Design-to-webpage in one click |
| Visual Debugging | Watch output, find and fix issues autonomously | No manual bug hunting |
| Chat-to-Interface | Describe needs in conversation, generate interactive UI with animations | Build webpages with zero coding knowledge |
Real-World Example: Show K2.5 Matisse’s “La Danse” painting, and it automatically generates a webpage with that artistic style—from color scheme to layout, fully automated.
Companion Tool: Kimi Code
Moonshot AI also launched Kimi Code terminal tool:
| Feature | Description |
|---|---|
| IDE Integration | Supports VSCode, Cursor, Zed, and other mainstream editors |
| Multimodal Input | Accepts images and videos as input |
| Open Source | Completely open-source and free to use |
| Auto-Migration | Automatically discovers and uses existing dev tools |
Core Capability 2: Agent Swarm - From Solo Work to Team Collaboration
Imagine this: You give AI a complex task, and instead of working alone slowly, it automatically summons 100 “assistants” to work simultaneously. That’s Agent Swarm.
How It Works (In Plain English)
| Traditional Single Agent | K2.5 Agent Swarm |
|---|---|
| One AI does tasks sequentially | Auto-distributes to 100 AIs working in parallel |
| Must finish step 1 before step 2 | All doable tasks start simultaneously |
| Like one person moving bricks | Like a construction crew collaborating |
| Time-consuming | Up to 4.5x faster |
Real Performance Comparison
| Metric | Single Agent | Agent Swarm | Improvement |
|---|---|---|---|
| Runtime | 100% | 20% | 80% reduction |
| Critical Steps | 100% | 22-33% | 3-4.5x reduction |
| Parallel Tasks | 1 task | Up to 100 tasks | 100x |
| Tool Calls | Sequential | Up to 1,500 coordinated | Massive parallelization |
Auto-Division Example
Say you ask K2.5 to research “Latest Advances in Quantum Computing”:
       Orchestrator (Commander)
├─ AI Researcher → Search academic papers
├─ Physics Researcher → Analyze technical principles
├─ Fact Checker → Verify data accuracy
└─ Summary Expert → Integrate all information
These “assistants” work simultaneously, no waiting for the previous one to finish, dramatically boosting efficiency.
Technical Highlights
PARL Algorithm (Simple Explanation):
- Trains K2.5 to be “the boss” - knows how to delegate tasks
- Avoids “fake parallelism” - ensures real simultaneous work, not just pretending
- Dynamic adjustment - automatically decides how many assistants needed based on task difficulty
Core Capability 3: Office Automation - AI Assistant on Duty 24/7
K2.5 handles various office tasks like a professional assistant—fast and high-quality.
What Can It Do?
| Task Type | Specific Capabilities | Efficiency Boost |
|---|---|---|
| Document Processing | Word annotations, formatting | Hours → Minutes |
| Data Analysis | Excel pivot tables, financial modeling | Days → Hours |
| Academic Writing | 10,000-word papers, LaTeX equations | Auto-generated |
| Report Generation | 100-page documents, PPT creation | End-to-end completion |
Performance Improvement Data
Compared to previous generation K2 Thinking:
| Benchmark | Improvement | Description |
|---|---|---|
| AI Office Benchmark | +59.3% | Office document quality |
| General Agent Benchmark | +24.3% | Overall office capability |
Real Application Scenarios
Scenario 1: Data Analysis Report
- Input: A bunch of Excel data
- K2.5 automatically: Cleans data → Builds model → Generates charts → Writes analysis report
- Output: Complete Word report + data visualization
Scenario 2: Academic Paper
- Input: Research topic and reference materials
- K2.5 automatically: Literature review → Writes main text → Inserts formulas → Formats layout
- Output: Complete paper meeting academic standards
Product Availability
Kimi K2.5 is available via multiple channels:
- Kimi.com and Kimi App
- API interface
- Kimi Code terminal tool
Four Modes
Kimi.com and Kimi App now support 4 modes:
- K2.5 Instant: Quick response mode
- K2.5 Thinking: Deep reasoning mode
- K2.5 Agent: Agent mode with preconfigured tools
- K2.5 Agent Swarm (Beta): Agent swarm mode
Agent Swarm is currently in beta on Kimi.com, with free credits available for high-tier paid users.
Benchmark Performance: Let’s See How K2.5 Really Stacks Up
Honestly, after diving into these numbers, K2.5’s performance is genuinely impressive. Let’s break down how it compares head-to-head with the big players: GPT-5.2, Claude 4.5 Opus, Gemini 3 Pro, and DeepSeek V3.2.
I. Reasoning & Knowledge: Nailing Tool-Augmented Tasks
First up, the most critical metric—tool-augmented reasoning, which is what really matters in real-world applications:
| Benchmark | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | DeepSeek V3.2 |
|---|---|---|---|---|---|
| HLE-Full | 30.1 | 34.5 | 30.8 | 37.5 🏆 | 25.1 |
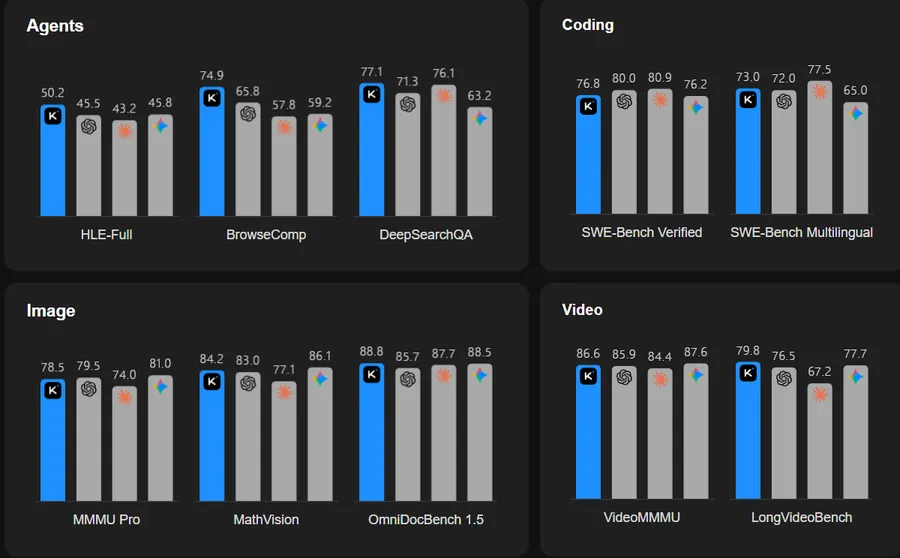
| HLE-Full w/ tools | 50.2 🏆 | 45.5 | 43.2 | 45.8 | 40.8 |
See that? Once you add tool calling into the mix, K2.5 jumps ahead—10.3% higher than GPT-5.2 and 16.2% above Claude 4.5. This shows K2.5’s real strength in multi-step reasoning and tool coordination.
Math Competition Scorecard:
| Test | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | DeepSeek V3.2 |
|---|---|---|---|---|---|
| AIME 2025 | 96.1 | 100.0 🏆 | 92.8 | 95.0 | 93.1 |
| HMMT 2025 | 95.4 | 99.4 🏆 | 92.9 | 97.3 | 92.5 |
| IMO-AnswerBench | 81.8 | 86.3 🏆 | 78.5 | 83.1 | 78.3 |
| GPQA-Diamond | 87.6 | 92.4 🏆 | 87.0 | 91.9 | 82.4 |
GPT-5.2 dominates math, but K2.5 holds its own in the top tier with a 96.1 on AIME—pretty close to perfect.
II. Vision Understanding: This is K2.5’s Home Turf
Here’s where things get interesting! K2.5 absolutely crushes it in vision, taking 9 first places out of 17 vision benchmarks:
Document Understanding Comparison (K2.5’s Absolute Advantage):
| Benchmark | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | Qwen3-VL |
|---|---|---|---|---|---|
| OCRBench | 92.3 🏆 | 80.7 | 86.5 | 90.3 | 87.5 |
| OmniDocBench 1.5 | 88.8 🏆 | 85.7 | 87.7 | 88.5 | 82.0 |
| InfoVQA | 92.6 🏆 | 84.0 | 76.9 | 57.2 | 89.5 |
| SimpleVQA | 71.2 🏆 | 55.8 | 69.7 | 69.7 | 56.8 |
K2.5 leads GPT-5.2 by 14.4% on OCRBench and leaves Gemini 3 Pro in the dust on InfoVQA. That’s the power of large-scale vision-text joint pretraining.
Video Understanding Comparison:
| Benchmark | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | Qwen3-VL |
|---|---|---|---|---|---|
| LongVideoBench | 79.8 🏆 | 76.5 | 67.2 | 77.7 | 65.6 |
| LVBench | 75.9 🏆 | — | — | 73.5 | 63.6 |
| MotionBench | 70.4 🏆 | 64.8 | 60.3 | 70.3 | — |
| MathVista (mini) | 90.1 🏆 | 82.8 | 80.2 | 89.8 | 85.8 |
Long video understanding? K2.5 leads the pack consistently.
III. Coding Capability: Best Open-Source, But Gap Remains with Top Closed-Source
Let’s be straight: K2.5 is the coding ceiling for open-source models, but in the coding arena, Claude 4.5 Opus still reigns supreme. Here’s the detailed breakdown:
Comprehensive Software Engineering Benchmark Comparison:
| Benchmark | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | DeepSeek V3.2 | Gap Analysis |
|---|---|---|---|---|---|---|
| SWE-Bench Verified | 76.8 | 80.0 | 80.9 🏆 | 76.2 | 73.1 | -5.3% behind |
| SWE-Bench Pro | 50.7 | 55.6 🏆 | 55.4 | — | — | -9.7% behind |
| SWE-Bench Multilingual | 73.0 | 72.0 | 77.5 🏆 | 65.0 | 70.2 | -6.2% behind |
| Terminal-Bench 2.0 | 50.8 | 54.0 | 59.3 🏆 | 54.2 | 46.4 | -16.7% behind |
| PaperBench | 63.5 | 63.7 | 72.9 🏆 | — | 47.1 | -14.8% behind |
| CyberGym | 41.3 | — | 50.6 🏆 | 39.9 | 17.3 | -22.5% behind |
| SciCode | 48.7 | 52.1 | 49.5 | 56.1 🏆 | 38.9 | -15.2% behind |
| LiveCodeBench (v6) | 85.0 | — | 82.2 | 87.4 🏆 | 83.3 | -2.8% behind |
Objective Assessment:
- Claude 4.5 Opus dominates coding - Takes 6 out of 9 first places in coding benchmarks, with clear advantages in complex software engineering tasks
- Gap widens on high-difficulty tasks - Terminal-Bench (terminal operations), PaperBench (research code), CyberGym (cybersecurity) show 15-23% gaps where deep reasoning matters
- Competitive in algorithm contests - Only 2.8% behind Gemini 3 Pro on LiveCodeBench, showing K2.5 holds its own in pure algorithmic challenges
- Strongest among open-source - Consistently outperforms DeepSeek V3.2 across all coding benchmarks
Why This Gap Exists?
Honestly, coding—especially complex software engineering—requires:
- Deep code understanding and reasoning
- Multi-file, multi-module coordination
- Edge case handling
- Code security and robustness considerations
Claude 4.5 Opus simply excels in these areas, which is why it maintains leadership in the SWE-Bench series (real-world software engineering tasks).
Where K2.5 Shines in Coding?
Despite the overall gap, K2.5 has unique strengths:
- Visual coding capability - Generating code from images/videos is K2.5’s unique advantage
- Front-end development - Officially emphasized strength, especially interactive interfaces and animations
- Tool collaboration - Combined with Kimi Code and Agent Swarm, potentially more practical in real development workflows
- Open-source availability - At 76.8 on SWE-Bench Verified, remarkably close to top closed-source levels for an open-source model
Practical Usage Recommendations:
| Scenario | Recommended Model | Reasoning |
|---|---|---|
| Complex software engineering, refactoring | Claude 4.5 Opus | Comprehensive lead, especially on complex tasks |
| Front-end dev, visual-to-code | K2.5 | Strong visual coding, Agent Swarm boost |
| Algorithm contests, competitive programming | Gemini 3 Pro / K2.5 | Minimal gap, both capable |
| Open-source deployment needed | K2.5 | Strongest open-source option |
| Multimodal coding tasks | K2.5 | Native image/video input support |
IV. Agent Swarm: K2.5’s Secret Weapon
This is where K2.5 really shines—Agent Swarm mode, a capability other models simply don’t have:
BrowseComp Three-Mode Comparison:
| Mode | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | DeepSeek V3.2 |
|---|---|---|---|---|---|
| Base | 60.6 🏆 | — | 37.0 | 37.8 | 51.4 |
| Context Mgmt | 74.9 🏆 | 65.8 | 57.8 | 59.2 | 67.6 |
| Agent Swarm | 78.4 🏆 | — | — | — | — |
See that? With Agent Swarm enabled, K2.5 rockets to 78.4—other models don’t even have this mode!
Comprehensive Agentic Search Leadership:
| Benchmark | K2.5 | GPT-5.2 | Claude 4.5 | Gemini 3 Pro | DeepSeek V3.2 |
|---|---|---|---|---|---|
| DeepSearchQA | 77.1 🏆 | 71.3 | 76.1 | 63.2 | 60.9 |
| FinSearchCompT2&T3 | 67.8 🏆 | — | 66.2 | 49.9 | 59.1 |
| Seal-0 | 57.4 🏆 | 45.0 | 47.7 | 45.5 | 49.5 |
| WideSearch (Single) | 72.7 | — | 76.2 🏆 | 57.0 | 32.5 |
| WideSearch (Agent Swarm) | 79.0 🏆 | — | — | — | — |
Financial search, deep search, wide search—K2.5 dominates across the board. Agent Swarm’s parallel collaboration advantage is crystal clear in complex tasks.
V. Overall Capability Radar
| Capability Dimension | K2.5 Rating | Core Highlights | Competitive Edge |
|---|---|---|---|
| Vision Understanding | ⭐⭐⭐⭐⭐ | 9 out of 17 firsts | OCR leads by 14.4%, video understanding dominance |
| Tool-Augmented Reasoning | ⭐⭐⭐⭐⭐ | HLE w/ tools 50.2 | Leads all models by 10%+ |
| Agentic Search | ⭐⭐⭐⭐⭐ | Exclusive Agent Swarm | BrowseComp 78.4, unmatched |
| Coding Capability | ⭐⭐⭐⭐ | Strongest open-source | Only 5% below top closed-source |
| Math Reasoning | ⭐⭐⭐⭐ | AIME 96.1 | Top tier, near-perfect |
| Long Context | ⭐⭐⭐⭐ | Stable & reliable | Mainstream level |
Bottom Line: What Makes K2.5 Stand Out?
After crunching all these numbers, a few things are crystal clear:
- Vision capability is genuinely powerful - Document OCR and video understanding show complete dominance—that’s native multimodal advantage
- Agent Swarm opens new possibilities - This exclusive capability gives K2.5 a serious edge in complex tasks, with up to 4.5x performance boost
- Tool calling champion - HLE w/ tools leadership proves K2.5 is more practical in real-world scenarios
- New open-source benchmark - As an open-source model, overall performance rivals or even surpasses some major closed-source products
In plain English, K2.5 is that “all-rounder athlete”—maxed-out vision understanding, solid coding chops, plus Agent Swarm as the ultimate trump card. For scenarios requiring complex multimodal task handling, K2.5 is definitely one of the top choices right now.
Technical Significance and Future Outlook
Grounded in advances in coding with vision, agent swarms, and office productivity, Kimi K2.5 represents a meaningful step toward AGI for the open-source community, demonstrating strong capability on real-world tasks under real-world constraints.
Looking ahead, Moonshot AI will push further into the frontier of agentic intelligence, redefining the boundaries of AI in knowledge work.
Related Resources:
Core Innovation Summary:
| Innovation | Technical Solution | Performance Gain |
|---|---|---|
| Visual Coding | Large-scale vision-text joint pretraining | Strongest open-source coding model |
| Agent Swarm | PARL + Critical Steps optimization | 4.5x speedup |
| Office Automation | End-to-end tool coordination | 59.3% performance improvement |
| Multimodal Capability | 15T mixed token training | Native visual understanding |
More Articles