Introducing GPT-5.2: A Frontier Model Built for Professional Work and Long-Running Agents
GPT-5.2 is OpenAI’s newest model family for professional work and long-running agents, improving long-context reasoning, tool use, vision, and coding, plus updated API names and pricing.
Published 281 days ago. Content may be outdated.
On Dec 11, 2025, OpenAI released the GPT‑5.2 model family. In plain English: it’s built to actually get work shipped. If your day is spreadsheets, slides, code, screenshots, long documents, and multi-step workflows (including long-running agent tasks), GPT‑5.2 is positioned as the more reliable “doer.”
TL;DR
- Stronger for real deliverables: On GDPval (knowledge-work tasks across 44 jobs), GPT‑5.2 Thinking sets a new bar.
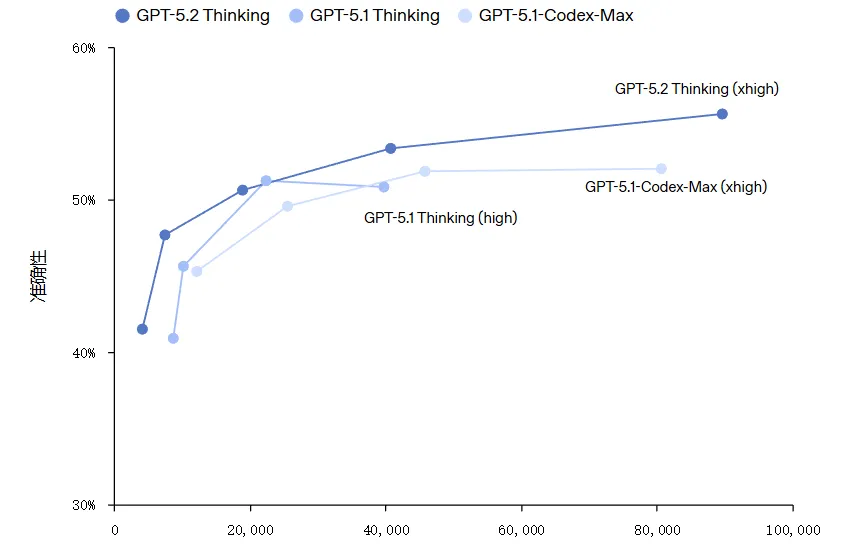
- Better at coding in practice: 55.6% on SWE-bench Pro (Public) and 80.0% on SWE-bench Verified.
- Fewer wrong answers: In de-identified ChatGPT queries, the share of responses with at least one error drops (6.2% vs 8.8%).
- Long context is a real advantage: Leads on long-context evals like OpenAI MRCRv2, including evaluations up to the 256k token input range.
- More reliable tool use: 98.7% on Tau2-bench Telecom, showing stronger multi-turn, multi-step tool workflows.
Benchmark snapshot (selected)
| Metric | GPT‑5.2 Thinking | GPT‑5.1 Thinking |
|---|---|---|
| GDPval (wins or ties) knowledge-work tasks | 70.9% | 38.8% (GPT‑5) |
| SWE-bench Pro (Public) software engineering | 55.6% | 50.8% |
| SWE-bench Verified software engineering | 80.0% | 76.3% |
| GPQA Diamond (no tools) science QA | 92.4% | 88.1% |
| CharXiv Reasoning (with Python) science charts | 88.7% | 80.3% |
| HMMT (Feb 2025) math contest | 99.4% | 96.3% |
| FrontierMath (Tier 1–3) advanced math | 40.3% | 31.0% |
| ARC-AGI-1 (Verified) abstract reasoning | 86.2% | 72.8% |
| ARC-AGI-2 (Verified) abstract reasoning | 52.9% | 17.6% |
GDPval: “Can it produce real work?”
GDPval is not a typical “solve a puzzle” benchmark. It asks models to produce realistic work outputs (think sales decks, accounting spreadsheets, staffing schedules, manufacturing charts, short-form video assets) across 44 professions.
GPT‑5.2 Thinking scores 70.9% wins-or-ties against top industry professionals on clearly defined knowledge-work tasks. OpenAI also estimates that, with human oversight, the model can deliver GDPval-style outputs more than 11× faster at under 1% of the cost (based on historical metrics).
Coding: fewer “looks right” patches, more “actually works”
If you’ve used models for coding, you know the pain: the output can look convincing but still break builds or miss edge cases. SWE-bench tries to measure the real thing by giving a repo and expecting a working patch.
GPT‑5.2 Thinking hits 55.6% on SWE-bench Pro (Public) and 80.0% on SWE-bench Verified.
In day-to-day engineering terms, this should translate into better odds of:
- Debugging production issues
- Implementing features end-to-end
- Refactoring larger codebases
- Shipping fixes with fewer back-and-forth cycles
Factuality: fewer errors, still verify critical work
On de-identified ChatGPT queries, OpenAI reports the “at least one error” rate dropping:
- GPT‑5.2 Thinking: 6.2%
- GPT‑5.1 Thinking: 8.8%
It’s an improvement, but it’s still not perfect—double check anything high-stakes.
Long context: better at connecting the dots
GPT‑5.2 Thinking is positioned as a new high-water mark for long-context reasoning. On OpenAI MRCRv2 (which tests whether a model can stitch together scattered information across very long documents), it performs strongly, including evaluation ranges up to 256k tokens.
For extra-long workflows that rely on tools, GPT‑5.2 Thinking can also pair with the Responses API /compact endpoint to extend the effective context window.
Vision: charts and UI screenshots get easier
Vision is framed as another major step forward—especially for chart reasoning and understanding GUI screenshots.
- CharXiv Reasoning (with Python): 88.7% (vs 80.3%)
- ScreenSpot-Pro (with Python): 86.3% (vs 64.2%)
Tool use: multi-step workflows that don’t fall apart
Tau2-bench measures whether a model can keep a multi-turn “support-style” conversation on track while using tools to actually resolve the case.
- Tau2-bench Telecom: 98.7%
- Tau2-bench Retail: 82.0%
Practically, this hints at fewer broken chains when your workflow needs “fetch data → analyze → update systems → generate final output.”
Availability & pricing (API)
API model names:
- GPT‑5.2 Thinking:
gpt-5.2 - GPT‑5.2 Instant:
gpt-5.2-chat-latest - GPT‑5.2 Pro:
gpt-5.2-pro
Pricing per 1M tokens:
| Model | Input | Cached input | Output |
|---|---|---|---|
| gpt-5.2 / gpt-5.2-chat-latest | $1.75 | $0.175 | $14 |
| gpt-5.2-pro | $21 | - | $168 |
Wrap-up
The story of GPT‑5.2 is pretty straightforward: it’s optimized for longer, messier, real-world work—the kind where you need consistent reasoning, solid tool usage, and outputs that look and feel like something you’d actually ship.
More Articles