GLM-Image: First Open-Source Industrial-Grade Autoregressive Image Model
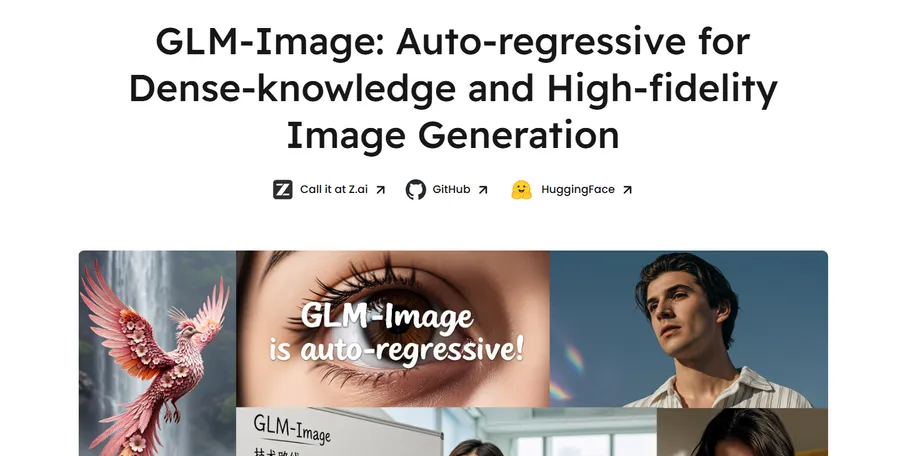
GLM-Image is the first open-source industrial-grade discrete autoregressive image generation model with hybrid architecture. Excels in text rendering and knowledge-intensive scenarios with 97.88% Chinese text accuracy.
Published 612 days ago. Content may be outdated.
1. 🚀 Introducing GLM-Image
Zhipu AI recently released GLM-Image, the first open-source industrial-grade discrete autoregressive image generation model. What makes it special? It’s particularly good at handling scenarios that require precise text rendering, like posters, presentations, and infographics.
What Makes It Special?
- Hybrid Architecture: Combines a 9B-parameter autoregressive module (based on GLM-4-9B) with a 7B-parameter diffusion decoder
- Superior Text Rendering: Ranks #1 among open-source models on CVTG-2K and LongText-Bench, achieving 97.88% accuracy for Chinese text
- Knowledge-Intensive Generation: Excels at scenarios requiring accurate expression of complex information, not just visual appeal
- Rich Features: Supports text-to-image, image editing, style transfer, and more
Official Resources:
- 🤗 Hugging Face: zai-org/GLM-Image
- 📦 ModelScope: ZhipuAI/GLM-Image
- 📖 Technical Blog: GLM-Image Technical Blog
2. Technical Architecture: Why This Design?
2.1 The Hybrid Approach
Traditional diffusion models generate high-quality images but struggle with complex instructions and accurate text rendering. GLM-Image’s team came up with a solution: split the task into two parts.
- Autoregressive Generator (9B params): Based on GLM-4-9B, responsible for “understanding” what you want and generating semantic-VQ tokens
- Diffusion Decoder (7B params): Uses CogView4 architecture to “paint” these tokens into high-quality images
Think of it like having someone sketch out your idea first, then an artist refining it into a masterpiece. This division of labor allows the model to both accurately understand complex instructions and generate high-quality details.
2.2 Key Technical Points
Semantic-VQ Tokens: Choosing the Right “Language”
GLM-Image uses semantic-VQ for visual tokenization. Simply put, it converts images into a “language” the model can understand. Compared to traditional VQVAE, this approach has lower training loss (about 3 vs 7), stronger semantic correlation, and is better suited for autoregressive modeling.
Progressive Generation: Layout First, Details Later
When generating high-resolution images, GLM-Image first creates a low-resolution version (about 256 tokens) to establish the overall layout, then generates high-resolution details (1024-4096 tokens). This approach provides better layout control and prevents the generation from “going off track.”
Glyph-byT5: Solving the “Character Amnesia” Problem
To enable accurate text rendering (especially Chinese characters), GLM-Image introduces a lightweight Glyph-byT5 model for character-level encoding. This is why it performs so well in text rendering.
Decoupled Reinforcement Learning: Clear Division of Labor
During post-training, GLM-Image uses the GRPO algorithm to separately optimize both modules:
- Autoregressive module focuses on semantic accuracy and aesthetic scoring
- Diffusion decoder focuses on detail quality and text precision
This “clear division of labor” training approach allows each module to maximize its potential.
3. Quick Start
3.1 Environment Setup
First, install the latest versions of transformers and diffusers, as GLM-Image uses some new features:
       pip install git+https://github.com/huggingface/transformers.git
pip install git+https://github.com/huggingface/diffusers.git
Hardware Requirements: Python 3.8+, CUDA 11.8+, at least 24GB GPU memory (you can try lower resolutions if memory is limited)
3.2 Generate Your First Image
The code is straightforward - just load the model and call it:
       import torch
from diffusers.pipelines.glm_image import GlmImagePipeline

# Load model
pipe = GlmImagePipeline.from_pretrained(
    "zai-org/GLM-Image",
    torch_dtype=torch.bfloat16,
    device_map="cuda"
)

# Generate image
prompt = "A cute panda eating bamboo in a bamboo forest, ink painting style"
image = pipe(
    prompt=prompt,
    height=32 * 32,  # 1024px, must be multiple of 32
    width=32 * 32,
    num_inference_steps=50,  # More steps = better quality but slower
    guidance_scale=1.5,      # Controls how closely the image matches the prompt
    generator=torch.Generator(device="cuda").manual_seed(42),
).images[0]

image.save("output.png")
3.3 Image Editing
GLM-Image also supports reference-based image editing, like changing backgrounds:
       from PIL import Image

# Load the image you want to edit
reference_image = Image.open("input.jpg").convert("RGB")

# Tell the model what you want to change
edited_image = pipe(
    prompt="Replace the snowy forest background with a subway station",
    image=[reference_image],  # Can pass multiple images
    height=33 * 32,
    width=32 * 32,
    num_inference_steps=50,
    guidance_scale=1.5,
).images[0]

edited_image.save("edited.png")
A Few Tips:
heightandwidthmust be multiples of 32 (model architecture requirement)num_inference_stepsof 50 is recommended for a good balance of quality and speedguidance_scaleof 1.5 is recommended; too high may cause overfitting
4. How Good Is the Performance?
4.1 Text Rendering: The Strong Suit
GLM-Image’s most impressive feature is its text rendering capability, ranking #1 among open-source models in multiple benchmarks:
CVTG-2K Test (Complex Visual Text Generation):
- Average Word Accuracy: 0.9116 (Open-source #1)
- NED Score: 0.9557 (Open-source #1)
Performance across multi-region text generation is consistently strong:
- 2 regions: 91.03%
- 3 regions: 92.09%
- 4 regions: 91.69%
- 5 regions: 89.75%
For comparison, FLUX.1 averages only 49.65%, and SD3.5 Large is at 65.48% - the gap is quite significant.
LongText-Bench Test (Long Text Rendering):
- English: 0.9524 (Open-source #1)
- Chinese: 0.9788 (Open-source #1)
Achieving 97.88% accuracy for Chinese text rendering is quite impressive. The test covers 8 common scenarios including signboards, posters, presentations, and dialog boxes.
4.2 General Image Generation: Holds Its Own
While GLM-Image focuses on text rendering, it doesn’t fall short in general image generation:
OneIG-Bench:
- English: 0.528 (Alignment 0.805, Text Understanding 0.969)
- Chinese: 0.511 (Alignment 0.738, Text Understanding 0.976)
DPG-Bench:
- Overall: 84.78
- Global Understanding: 87.74
- Entity Recognition: 90.25
- Relation Reasoning: 92.15
TIFF-Bench:
- Short Text: 81.01
- Long Text: 81.02
Overall, it matches mainstream latent diffusion models in general image generation quality, but clearly leads in text rendering and knowledge-intensive scenarios.
5. Wrapping Up
GLM-Image is an interesting attempt that goes beyond just generating pretty pictures - it aims to help AI “articulate” complex information clearly. Through its hybrid autoregressive + diffusion architecture, it achieves top-tier performance among open-source models in text rendering, with 97.88% accuracy for Chinese text. This is quite practical for scenarios requiring posters, presentations, or infographics.
Key Highlights:
- Clever architecture design that separates “understanding” from “painting”
- Genuinely strong text rendering capability, especially for Chinese
- Fully open-source (MIT license), commercially usable
- Not just image generation - also supports editing and style transfer
From a technical perspective, GLM-Image represents a new direction: from “pure visual generation” to “cognitive generation.” Future image generation models may not just paint beautifully, but also “understand” what you want to express and accurately visualize complex information. This opens up significant possibilities for education, business, and science communication.
If you have text rendering needs or want to do knowledge-intensive image generation, GLM-Image is worth trying out.
Related Resources:
More Articles