DeepSeek-V4: 1M Context, Best Open-Source Agent, Beats Claude Sonnet 4.5
DeepSeek-V4 released with 1M context as standard! Agent capabilities surpass open-source models, reasoning performance rivals GPT-4o and Claude Opus.
Published 158 days ago. Content may be outdated.
On April 24, 2026, DeepSeek officially released the all-new DeepSeek-V4 series and simultaneously open-sourced it.
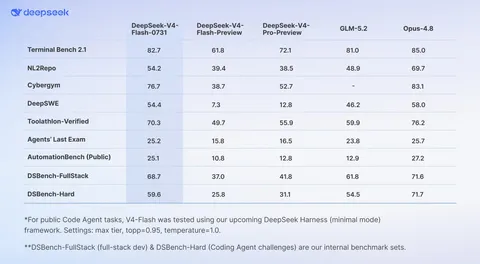
Key metrics: 1M (million token) context as standard, achieving best level among open-source models in Agentic Coding evaluation, surpassing all publicly evaluated open-source models in math, STEM, and competitive coding tests.
In practical use, DeepSeek-V4-Pro performs better than Claude Sonnet 4.5, with delivery quality approaching Claude Opus 4.6 non-thinking mode. The model has already become the primary Agentic Coding tool used by DeepSeek’s internal employees.
Starting today, 1M context becomes the standard configuration for all DeepSeek official services.
Two Versions: Pro and Flash, Each with Strengths
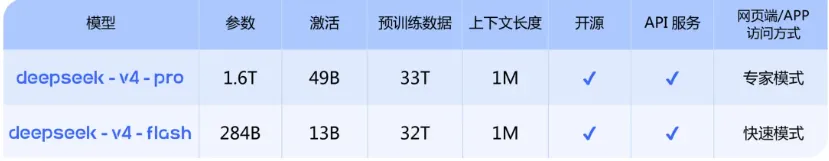
DeepSeek-V4 comes in two sizes to meet different scenario needs:
| Version | Positioning | Core Advantages | Use Cases |
|---|---|---|---|
| DeepSeek-V4-Pro | Flagship | Strongest Agent capabilities, top-tier reasoning, rich world knowledge | Complex Agent tasks, high-difficulty reasoning, professional Q&A |
| DeepSeek-V4-Flash | Economy | Reasoning close to Pro, faster speed, lower cost | Simple Agent tasks, daily conversations, batch processing |
Both versions come standard with 1M context and support Thinking Mode (Reasoning Mode).
DeepSeek-V4-Pro: Performance Rivals Top Closed-Source Models
1. Significantly Enhanced Agent Capabilities
Here’s the key: DeepSeek-V4-Pro’s Agent capabilities are significantly enhanced.
Agentic Coding Evaluation Performance:
- Achieved the best level among current open-source models
- User experience superior to Claude Sonnet 4.5
- Delivery quality approaching Claude Opus 4.6 non-thinking mode
- Still has some gap with Opus 4.6 thinking mode
The data doesn’t lie: DeepSeek-V4 has become the Agentic Coding model used by DeepSeek’s internal employees.
Excellent Performance Across Agent Evaluations:
- Improved code task performance
- Improved document generation task performance
- Specialized optimization for mainstream Agent products like Claude Code, OpenClaw, OpenCode, CodeBuddy
2. Rich World Knowledge
DeepSeek-V4-Pro in world knowledge evaluation:
- Significantly leads other open-source models
- Only slightly behind top closed-source model Gemini-Pro-3.1
Simply put, its knowledge base is already approaching Google’s top model.
3. World-Class Reasoning Performance
In math, STEM, and competitive coding evaluations, DeepSeek-V4-Pro:
- Surpasses all currently publicly evaluated open-source models
- Achieved performance rivaling world-class closed-source models
| Capability Dimension | DeepSeek-V4-Pro | Comparison |
|---|---|---|
| Math Reasoning | ✅ Surpasses all open-source | Rivals GPT-4o, Claude Opus |
| STEM Reasoning | ✅ Surpasses all open-source | Rivals top closed-source |
| Competitive Code | ✅ Surpasses all open-source | Rivals top closed-source |
| World Knowledge | ✅ Significantly leads open-source | Only slightly behind Gemini-Pro-3.1 |
| Agent Capabilities | ✅ Best among open-source | Superior to Sonnet 4.5, approaching Opus 4.6 |
DeepSeek-V4-Flash: Faster and More Economical Choice
DeepSeek-V4-Flash is positioned as balancing speed and cost:
Performance:
- World knowledge slightly behind Pro
- Reasoning ability close to Pro
- On par with Pro on simple Agent tasks
- Still has gap on high-difficulty Agent tasks
Core Advantages:
- Smaller model parameters and activation
- Provides faster, more economical API service
- Also supports 1M context and thinking mode
Simply put, choose Flash for daily use, Pro for complex tasks.
Black Tech: Novel Attention Mechanism + DSA Sparse Attention
Most eye-catching is DeepSeek-V4’s structural innovation.
Core Technical Breakthrough
DeepSeek-V4 pioneered a novel attention mechanism:
- Compression at token dimension
- Combined with DSA Sparse Attention (DeepSeek Sparse Attention)
- Achieved globally leading long-context capability
Technical Advantages:
- Significantly reduced computational requirements compared to traditional methods
- Significantly reduced memory requirements compared to traditional methods
- Supports 1M context as standard
Performance Comparison
| Comparison Dimension | DeepSeek-V4 | Traditional Methods |
|---|---|---|
| Computation | ✅ Significantly reduced | ❌ Linear growth with context length |
| Memory Capacity | ✅ Significantly reduced | ❌ Linear growth with context length |
| Context Length | ✅ 1M standard | ❌ Usually 32K-128K |
From now on, 1M (million) context will be standard for all DeepSeek official services.
Specialized Agent Capability Optimization
DeepSeek-V4 has been adapted and optimized for mainstream Agent products:
| Agent Product | Optimization |
|---|---|
| Claude Code | Code tasks, document generation |
| OpenClaw | Agent framework adaptation |
| OpenCode | Code generation optimization |
| CodeBuddy | Programming assistant optimization |
Practical Application Scenarios:
- Improved code task performance
- Improved document generation task performance
- Supports generating complex documents like PPTs and reports
How to Use? Three Options
1. Online Chat
Visit chat.deepseek.com or the official App to chat with the latest DeepSeek-V4 and explore the new experience of 1M ultra-long context memory.
2. API Calls
API service has been updated synchronously, supporting:
- OpenAI ChatCompletions interface
- Anthropic interface
Calling Method:
       # base_url unchanged, just modify model_name
model_name = "deepseek-v4-pro"  # or "deepseek-v4-flash"
Core Parameters:
- Maximum context length: 1M
- Supports non-thinking mode and thinking mode
- Thinking mode supports
reasoning_effortparameter to set thinking intensity (high/max)
Usage Recommendations:
- For complex Agent scenarios, recommend using thinking mode
- Set thinking intensity to max
3. Local Deployment
DeepSeek-V4 is simultaneously open-sourced, supporting local deployment:
Open Source Links:
- Hugging Face: https://huggingface.co/collections/deepseek-ai/deepseek-v4
- ModelScope: https://modelscope.cn/collections/deepseek-ai/DeepSeek-V4
Technical Report:
Important Notice: Old Interfaces Will Be Deprecated
Please note: Two old API interface model names will stop working on July 24, 2026:
deepseek-chat→ will point todeepseek-v4-flashnon-thinking modedeepseek-reasoner→ will point todeepseek-v4-flashthinking mode
Recommend migrating to new model names as soon as possible.
What Can It Do? Countless Scenarios
| Application Scenario | Core Capability | Practical Value |
|---|---|---|
| Agentic Coding | Code generation, debugging, refactoring | Boost development efficiency, code quality approaching human experts |
| Document Generation | PPTs, reports, technical docs | Automated content creation, save massive time |
| Long Text Analysis | 1M context understanding | Analyze entire books, complete codebases, long papers |
| Complex Reasoning | Math, STEM, competitive code | Solve high-difficulty problems, assist research and learning |
| Knowledge Q&A | Rich world knowledge | Professional domain consulting, knowledge retrieval |
| Thinking Mode | Deep reasoning | Handle complex logic, provide detailed thinking process |
Final Thoughts
The release of DeepSeek-V4 marks the official arrival of the million-context universal era.
It’s no longer about “having long context” to call yourself a long-context model, but achieving: 1M context standard + top-tier reasoning + powerful Agent capabilities + fully open-source.
More importantly, DeepSeek not only released the model but also provided complete API services and open-source weights. Developers can get started immediately, no waiting.
From Agent capabilities perspective, DeepSeek-V4-Pro has reached a level superior to Claude Sonnet 4.5 and approaching Opus 4.6 non-thinking mode. This means open-source models can now compete with top closed-source models in the Agent domain.
From technical innovation perspective, the novel attention mechanism + DSA sparse attention makes 1M context no longer a luxury but standard. The significant reduction in computation and memory requirements means more developers can access ultra-long context capabilities.
The future of AGI may come faster than we think.
More Articles