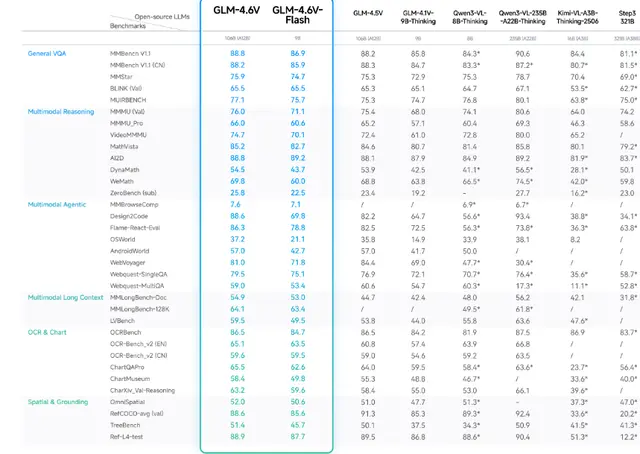
GLM-4.6V: Free Open Source Multimodal AI Model - Download & Usage Guide
GLM-4.6V free open-source multimodal AI model guide. 106B/9B versions, 128K context, image recognition, OCR, PDF understanding, video analysis.
6 articles
Compare OCR tools and models for document text, tables and formulas, with practical setup and local deployment guides.
Distinguish scanned documents, native PDFs and scene images before choosing a tool for the language, layout and hardware. Test reading order, table structure and formula output as well as text accuracy.
GLM-4.6V free open-source multimodal AI model guide. 106B/9B versions, 128K context, image recognition, OCR, PDF understanding, video analysis.
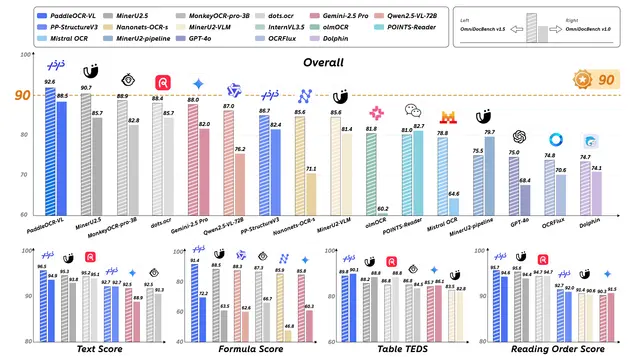
PaddleOCR-VL Tutorial: Baidu 0.9B AI model for 109-language OCR. Parse text, tables, formulas & charts with Docker/Python API. SOTA performance beats GPT-4V.
vLLM now supports Xiaohongshu's dots.ocr for free multilingual OCR. Follow our tutorial to deploy this powerful model in two steps for parsing text, tables, and formulas.
IBM Research's SmolDocling, a 256M-parameter vision-language model, delivers fast document OCR and multimodal processing at 0.35s per page on consumer GPUs, handling text, formulas, code and charts efficiently.
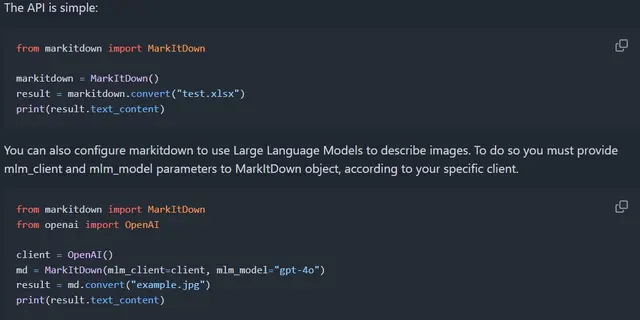
MarkItDown Tutorial - Microsoft AI-powered document conversion tool: supports PDF, Office documents, images, audio and other formats, with OpenAI integration for intelligent descriptions
A detailed tutorial on how to use MinerU, including online experience and local deployment methods. Supports extracting text, images, tables, and mathematical formulas from PDF documents, suitable for academic research, data analysis, and more.