Kimi K3 Goes Open-Weight: How 2.8T Activates Just 104B Parameters
Kimi K3's full weights and 47-page technical report are out. We unpack its 2.8T MoE, 104B active parameters, 1M context, agent RL, deployment demands, and license limits.
9 articles
Understand MoE architecture, total versus active parameters, and the deployment implications of related model releases.
Distinguish total parameters, active parameters and actual memory use when comparing MoE models. Consider quantization, expert parallelism and framework support instead of estimating deployment cost from active parameters alone.
Kimi K3's full weights and 47-page technical report are out. We unpack its 2.8T MoE, 104B active parameters, 1M context, agent RL, deployment demands, and license limits.
Qwen releases Qwen3.6-35B-A3B with enhanced agentic coding and frontend workflow capabilities. New thinking preservation feature maintains context across conversations. Built on Qwen3.5 architecture with MoE + sparse activation, supports 201 languages, Apache 2.0 licensed.
Google releases Gemma 4 multimodal models with dense and MoE architectures, 256K token context, native reasoning mode, and deployment from mobile to server. Four model sizes available under Apache 2.0.
Qwen3.5-Omni: Native multimodal model with 256k context, 10-hour audio, 4M frame video support. Thinker-Talker + Hybrid-Attention MoE architecture achieves SOTA in 215 benchmarks.
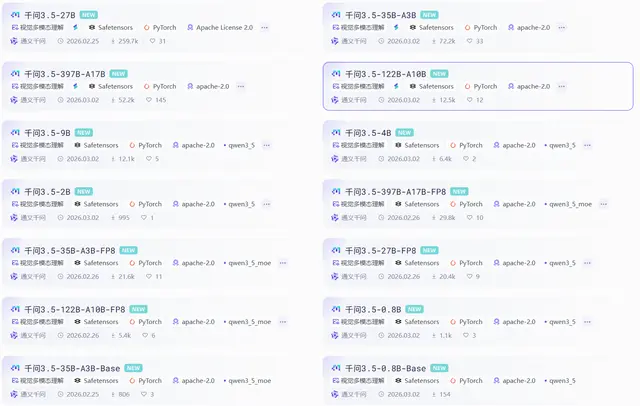
Qwen3.5 MoE series (0.8B-397B) with Gated DeltaNet hybrid attention. 9B outperforms 120B models, 0.8B processes video on smartphones. 1M context, native multimodal, 201 languages.
Qwen3-Omni-modal model for text, image, audio and video with real-time speech. Thinker–Talker + MoE, multi-codebook for low latency; 119 languages; vLLM/Transformers tips.
Qwen3-Next series: a hybrid architecture with Gated DeltaNet × Gated Attention. 80B total parameters with ~3B active per step, optimized for long context, high concurrency, and low latency. Instruct and Thinking target production chat and deep reasoning respectively.
Introducing Alibaba Cloud's Qwen3 LLM series (0.6B-235B), featuring MoE and Dense architectures for optimal performance and efficiency. Supports 119 languages with advanced coding and math capabilities.
"DeepSeek open-sources its inference engine with vLLM integration, featuring expert parallelism and MLA optimization. A milestone for AI infrastructure standardization and community collaboration."