DeepSeek Harness Is Open: The Agent Runtime Is Now a Plugin Tree
DeepSeek Harness is an open Agent runtime from DeepSeek AI, powered by Cordis. It turns models, tools, sessions, sandboxes, and the Agent Loop into composable plugins.
9 articles
Follow DeepSeek releases and technical reports, comparing reasoning capabilities, API usage and local inference options.
Identify the model version and reasoning mode you need, then check API or local deployment requirements. Use the release analyses and inference guides below, verifying current pricing and availability with the official provider.
DeepSeek Harness is an open Agent runtime from DeepSeek AI, powered by Cordis. It turns models, tools, sessions, sandboxes, and the Agent Loop into composable plugins.
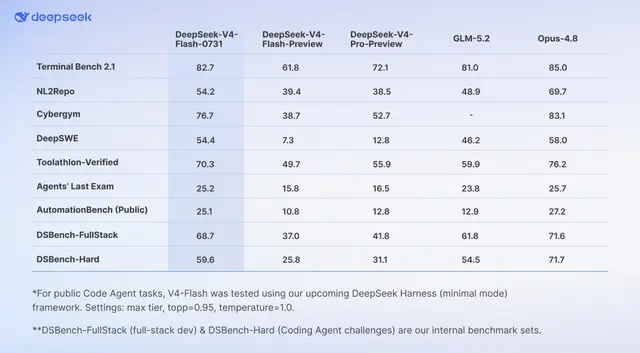
DeepSeek-V4-Flash reaches 82.7 on Terminal-Bench 2.1, beats GLM-5.2, approaches Claude Opus 4.8, and costs just ¥1 input / ¥2 output per million tokens for agents.
According to estimates cited from the Bloomberg Billionaires Index, DeepSeek founder Liang Wenfeng's net worth has risen to about $36 billion, making him arguably the world's richest founder of an AI-native startup.
DeepSeek is reportedly seeking up to $7.35B while planning new revenue efforts. The real shift is not funding itself, but the move from open-weight momentum to commercial pressure.
DeepSeek-V3.2 is the latest open-source LLM rivaling GPT-5 and Gemini-3.0-Pro, featuring DSA sparse attention and gold-medal results in IMO/IOI 2025.
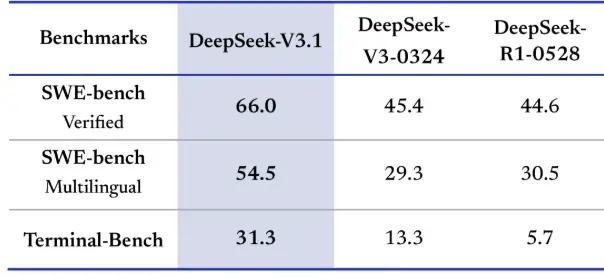
DeepSeek V3.1 adds Think/Non‑Think hybrid reasoning, stronger coding and Agent abilities, 128K context and MoE efficiency, plus Anthropic API support for Claude Code.
"DeepSeek open-sources its inference engine with vLLM integration, featuring expert parallelism and MLA optimization. A milestone for AI infrastructure standardization and community collaboration."
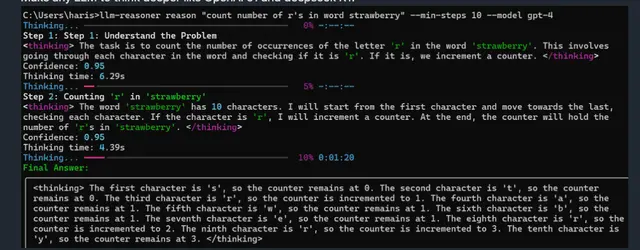
Learn to implement LLM-Reasoner framework for enhanced logical reasoning like DeepSeek R1. Step-by-step guide for building AI systems with advanced thinking capabilities.
"Deep dive into DeepSeek-V3 model. Its architecture combines MLA and DeepSeekMoE with innovative load balancing. Trained on 14.8T tokens, powered by HAI-LLM framework and FP8 technology. Enhanced by innovations like MTP, performance surpasses open-source and approaches closed-source models. Cost-effective with low training and API costs, a key reference in AI advancing language models."